 @baekpica2
Exploring the Limits of Model Compression and Inference
Hi everyone, I'm Sunghoon Baek, an AI engineer based in South Korea.
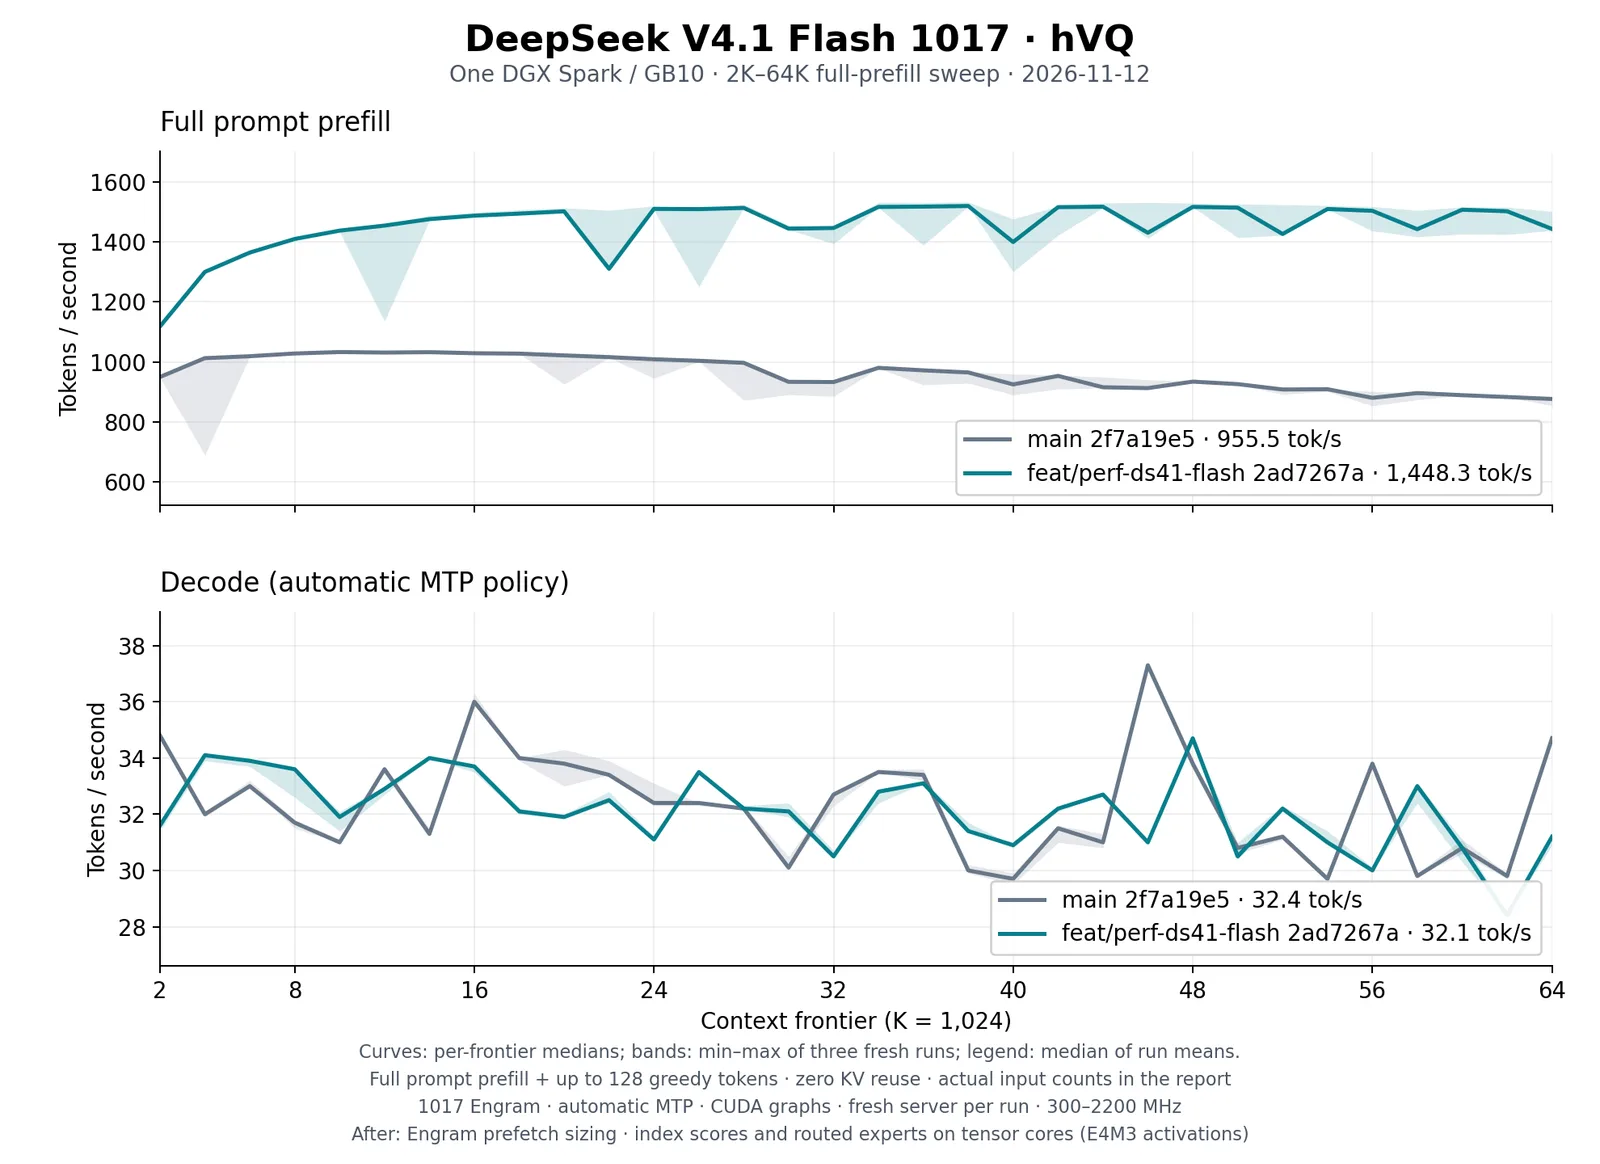
I work on model compression and inference optimization, mainly through my open-source project, ds4-dfm-rs.
With the help of AI agents, I've been exploring how far I can push model quantization, custom CUDA kernels, and inference performance as an individual developer.
My recent work focuses on aggressive vector quantization (VQ) and efficient inference on memory-constrained hardware. One example is running a compressed 501B-parameter MoE model on a single machine with 128GB of unified memory.
I'm particularly interested in how much redundancy exists in large models, and how much of their original capabilities we can preserve while substantially reducing memory and compute requirements.
I'd be interested in exchanging ideas, benchmark results, and technical feedback with others working on similar problems.
Glad to be here.








Comments
0 comments