 @madeinplutofabio4
A better model can make your agent worse
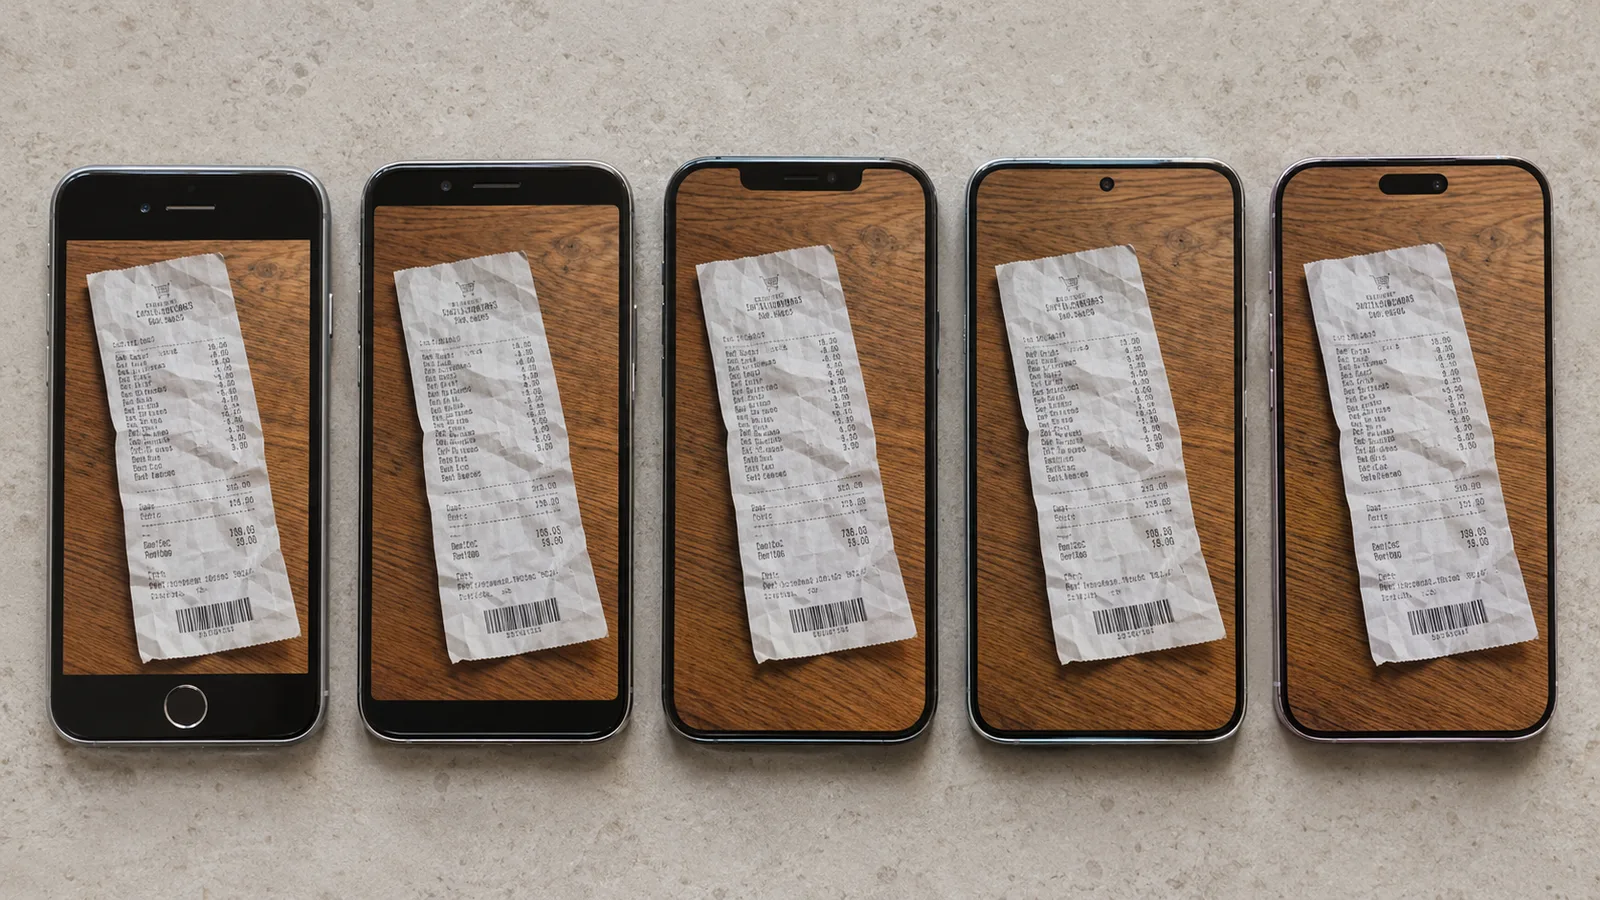
The new iPhone has a better camera, and yet I’m still taking pictures of receipts....So why shall I replace mine?
I think about that whenever a new model comes out, because what I want to know is never whether the model is better; it’s what changes for the workflow I already have running. Usually the answer is less than the launch post suggests. Sometimes things get worse, for reasons that have nothing to do with how good the new model is.
In October, more than half of the language-model requests on Vercel’s AI Gateway went to models less than 60 days old. About four weeks after a typical model hit its peak, roughly three quarters of the teams using it at that peak had stopped. That’s a lot of moving around. The report counts where requests went, not what anyone gained, so I read it as a picture of how much teams are experimenting, not as proof that each switch paid off.
The part I rarely see discussed is this: once an agent has been in production for a few months, almost everything around the model has been shaped by that model’s flaws.
Your prompt is a list of patches
Take a support agent that reads incoming emails, spots refund requests and sends them to an approval queue. Somewhere in its prompt you’ll find a line like “Do NOT ask the customer for their order number if it appears anywhere in the email,” written in capitals because at some point the model kept asking. Each of those lines fixes something the old model did wrong.
Newer models tend to follow instructions more literally (both OpenAI and Anthropic say so in their own prompting guides). So the new model reads that line and obeys it harder than you meant it. When the order number really is missing, it still won’t ask, and the ticket sits in the queue with nothing to look up. The instruction was right for the old model and wrong for the new one, and no benchmark would have told you.
Before testing a new model, I’d go through the prompt line by line and mark every instruction that exists because of something the old model did. Those are the first lines to remove, or at least the first to test.
Your tests were written by the old model’s mistakes
Most teams build their test set the same way: something breaks in production, and someone adds that case so it never happens again. After six months you have two hundred cases, and nearly all of them are things the old model got wrong.
That makes the test set very good at checking that a new model doesn’t repeat the old model’s mistakes; it says very little about the new model’s own mistakes, because nobody has had the chance to write those down yet. A new model can pass all two hundred cases and fail the following Tuesday in a way none of them covers. A clean run on the new model means less than the same score meant on the old one. Before trusting it, I’d run it on real tickets alongside the old model for a few days and have someone compare the two.
Your reviewers learned where to look
The people checking the agent’s work have adapted too. Say the old model left the refund reason blank whenever it was unsure. The team learned to check the blanks, which took ten seconds a ticket and caught most problems.
A more confident model fills in a reason every time, and it’s usually right. When it’s wrong, the reason sounds plausible, so the ticket looks like every other ticket. Accuracy goes up while the number of mistakes anyone actually catches goes down, because the review habit was built around a failure that no longer happens. That’s how a model can get more tickets right and still leave the team with more work: the extra cost comes from how hard each error is to spot, not from how many errors there are.
The price works the same way. A lower price per million tokens doesn’t guarantee a lower price per ticket, since models that reason before answering can spend far more tokens on the same email, and different models count the same text as different numbers of tokens to begin with. The only figure that tells you anything is the cost of a correctly handled ticket, measured on your own traffic.
Take the fragility out before you change the model
Now suppose the agent sometimes gets a discount wrong. You could spend a week looking for a model that does the arithmetic right more often, or you could calculate the discount in code and hand the agent the result. Whatever model you use next still has to work out what the customer is asking for; it just has one fewer way to get the refund wrong. The same goes for the refund itself: I’d have the system check the amount, currency and payment ID independently before anything goes out, whichever model sits in front of it.
I’d also switch only the part that benefits. A model that can untangle a long, messy billing dispute might be worth paying for on that one step, while the model that has been routing routine tickets reliably can keep routing them.
You’ll have to switch eventually anyway
Keeping the model that works has an expiry date. Providers retire old models on a published schedule, usually with a few months’ notice, so at some point the choice isn’t yours. If you call the model through an alias like “latest,” the switch may already have happened without you noticing; pinning a dated version is the first thing I’d check.
That’s the real reason to do this work now. If the patches in your prompt are labelled, your test set includes cases the old model got right as well as the ones it got wrong, and the checks on amounts happen in code, then the forced migration takes a week of testing instead of a scramble.
So when a new model comes out, I try to finish one of two sentences: “If we switch, we’ll finally be able to ,” or “If we switch, we’ll spend less on .” If I can, it’s worth a test, with the prompt cleaned up first and real tickets to compare. If I can’t, I keep the one that works and get ready for the day it’s retired.









Comments
0 comments